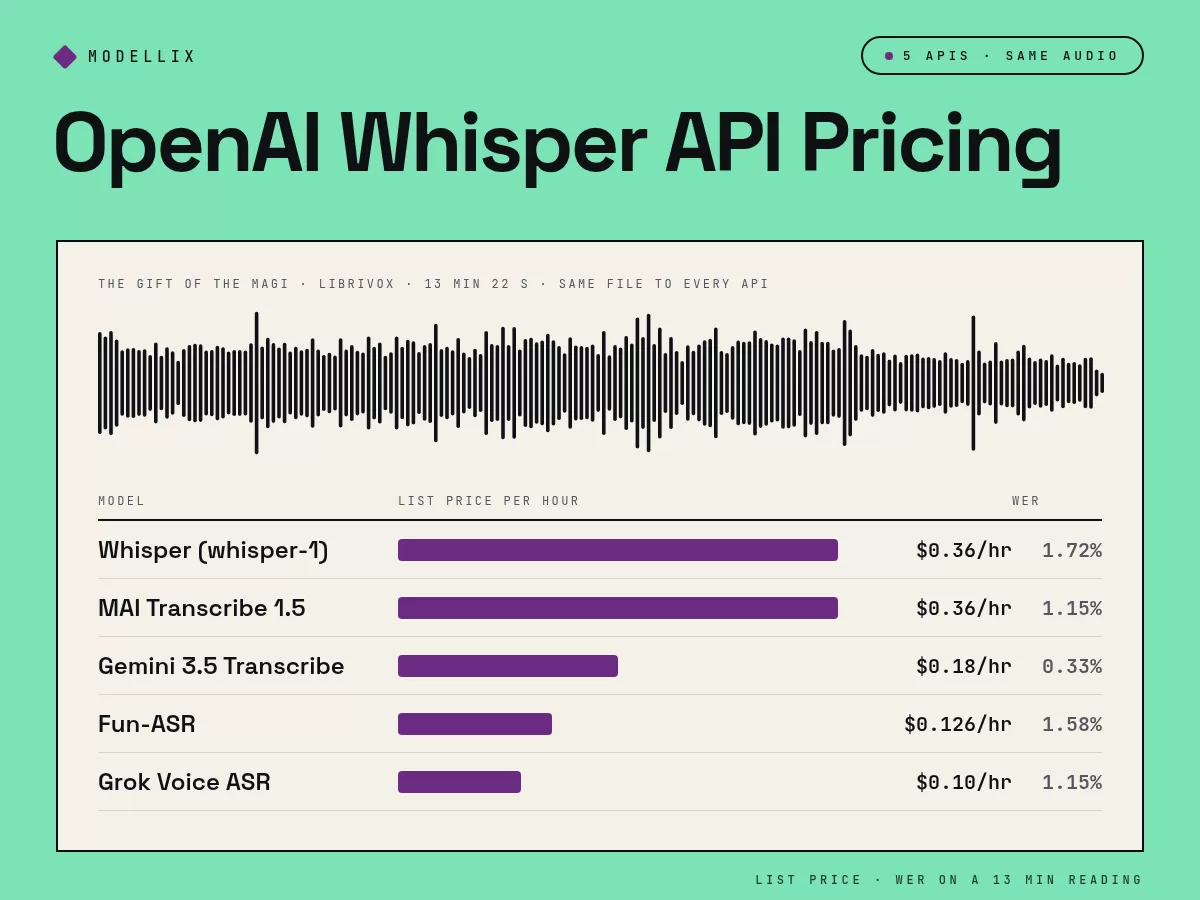
OpenAI Whisper API pricing is $0.006 per minute, or $0.36 per hour of audio. Two things make that number less simple than it looks. OpenAI now lists a cheaper file model, gpt-transcribe, at $0.0045 a minute, and whisper-1 shuts down on February 26, 2027, together with the endpoint that translates speech into English.
We sent the same four sets of audio to Whisper and four other speech-to-text models and recorded what each task billed: 39 completed tasks, 45 minutes of audio per model, $0.72 in total. Below are the price tables, how short files are billed, word error rates, the names each model got wrong, and the features you lose when Whisper goes away. If the shutdown notice brought you here, you need two answers: what Whisper costs until then, and which model to move to. The test is set up so you can rerun it on your own audio before you pick.
OpenAI Whisper API Pricing at a Glance: $0.006 a Minute
| OpenAI model | Use | Per minute | Per hour | Status |
|---|---|---|---|---|
whisper-1 |
Files, timestamps, SRT/VTT, translation | $0.006 | $0.36 | Shuts down 2027-02-26 |
gpt-4o-transcribe |
Files, higher accuracy | $0.006 | $0.36 | Shuts down 2027-02-26 |
gpt-4o-transcribe-diarize |
Files with speaker labels | $0.006 | $0.36 | Shuts down 2027-02-26 |
gpt-transcribe |
Files, recommended replacement | $0.0045 | $0.27 | Current |
gpt-4o-mini-transcribe |
Files, lowest price | $0.003 | $0.18 | Shuts down 2027-02-26 |
gpt-live-transcribe |
Live audio | $0.017 | $1.02 | Current |
gpt-realtime-whisper |
Live audio | $0.017 | $1.02 | Current |
gpt-realtime-translate |
Live speech translation | $0.034 | $2.04 | Current |
Source: OpenAI API pricing, Transcription section, and the deprecations page. OpenAI labels these per-minute figures as estimated cost. The 4o transcription models are billed by audio tokens underneath, at $2.50 per 1M input tokens for gpt-4o-transcribe and $1.25 for the mini model. For OpenAI's wider price list, including other API products, see OpenAI pricing plans.

Whisper API cost calculator: price per hour
Multiply hours of audio by the hourly rate. Rate limits and file size do not change the price.
| Audio per month | whisper-1 | gpt-transcribe | gpt-4o-mini-transcribe | Grok Voice ASR (list) |
|---|---|---|---|---|
| 1 hour | $0.36 | $0.27 | $0.18 | $0.10 |
| 10 hours | $3.60 | $2.70 | $1.80 | $1.00 |
| 100 hours | $36.00 | $27.00 | $18.00 | $10.00 |
| 1,000 hours | $360.00 | $270.00 | $180.00 | $100.00 |
Grok Voice ASR is the lowest list price among the five models we tested. Whisper costs 3.6 times as much for the same hour of audio.
Moving off whisper-1: four replacements we tested
- Lowest price per hour: Grok Voice ASR. $0.10 an hour list, 1.15% WER on the 13.4 minute reading, and it returned that file in 6 seconds; Whisper took 76. Try Grok Voice ASR
- Names and jargon: Gemini 3.5 Transcribe. Caught all 20 names and figures in the NASA clip, at $0.18 an hour list. Try Gemini 3.5 Transcribe
- Speaker turns at low cost: Fun-ASR. $0.126 an hour list, returned speaker turns with times, and billed only detected speech in our runs. Try Fun-ASR
- Same price, word timestamps: MAI Transcribe 1.5. $0.36 an hour like Whisper, with word level timestamps listed on its model page. Try MAI Transcribe 1.5
- One key for all five. Whisper and these four run on the same Modellix API key, so you can send one audio URL to each and compare before you switch. The steps are in the migration section below.
What Whisper Actually Bills: Short Files, File Limits, and Rate Limits
How short files are billed
OpenAI does not publish a rounding rule for its transcription API, so we measured one where we could. We cut four clips from the same LibriVox recording, 5, 31, 61, and 119 seconds long, and sent each once to every model on Modellix.

| Model on Modellix | 5 s clip | 31 s clip | 61 s clip | 119 s clip |
|---|---|---|---|---|
 Whisper |
$0.0005 | $0.0031 | $0.0061 | $0.0119 |
 MAI Transcribe 1.5 |
$0.0005 | $0.0031 | $0.0061 | $0.0119 |
 Gemini 3.5 Transcribe |
$0.0002 | $0.0015 | $0.0030 | $0.0059 |
 Fun-ASR |
$0.0001 | $0.0009 | $0.0019 | $0.0036 |
 Grok Voice ASR |
$0.0001 | $0.0008 | $0.0016 | $0.0033 |

None of the five models charged a full minute for a short clip. On Modellix, Whisper and MAI Transcribe 1.5 billed $0.0001 per second, so the 5 second clip cost $0.0005 instead of the $0.006 a one-minute minimum would charge. Gemini 3.5 Transcribe and Grok Voice ASR billed per second and cut the amount to four decimal places. These results describe Modellix billing only; they say nothing about how OpenAI bills its own endpoint.
Fun-ASR billed less than the file length on every clip. In our test runs, its charge matched the total length of the sentences it detected: 685.7 billed seconds against 685.6 seconds of detected speech on the 802 second reading, and 140 of 180 seconds on the podcast clip with its music intro. Silence and music were not billed in those tasks. Modellix has not published a formal rule that Fun-ASR bills only detected speech; the figures above are the observed charges from this test.
The 25 MB file limit
Whisper accepts files up to 25 MB in mp3, mp4, mpeg, mpga, m4a, wav, or webm (OpenAI speech-to-text guide). A 64 kbps mono mp3 fits about 50 minutes under that cap. Our 25.5 minute test file was 12.2 MB and went through in one task. For longer recordings, split the file and send the pieces; you pay for the same total minutes, but you need to stitch the text back together yourself.
Rate limits by usage tier
The whisper-1 model page lists 3 requests per minute and 200 per day on the Free tier, then 2,500, 7,500, and 10,000 requests per minute on the Build, Launch, and Grow tiers. Rate limits cap throughput; they do not change the price per minute.
whisper-1 Shuts Down on February 26, 2027: What to Migrate
OpenAI announced the deprecation on August 26, 2026. On February 26, 2027 these stop working: whisper-1, gpt-4o-transcribe, gpt-4o-mini-transcribe, gpt-4o-transcribe-diarize, and the /v1/audio/translations endpoint. OpenAI's recommended replacement for recorded audio is gpt-transcribe, and gpt-live-transcribe for live audio.
The swap to gpt-transcribe
For plain transcription, the change is the model name, and the price drops 25%, from $0.006 to $0.0045 a minute:
from openai import OpenAI

client = OpenAI()  # reads OPENAI_API_KEY from the environment
with open("meeting.mp3", "rb") as audio:
    result = client.audio.transcriptions.create(
        model="gpt-transcribe",  # was "whisper-1"
        file=audio,
    )
print(result.text)
The request still goes to POST /v1/audio/transcriptions. OpenAI's migration guide says not to assume that text, verbose_json, SRT, or VTT response formats stay valid on gpt-transcribe.
What has no OpenAI replacement yet
The OpenAI speech-to-text guide now says its examples for word timestamps, speaker labels, and subtitle formats use deprecated models. If your product depends on any of these, check where they will come from before 2027.
| Feature | whisper-1 | gpt-transcribe | Options on one key |
|---|---|---|---|
| Word and segment timestamps | Yes | No | Whisper, MAI Transcribe 1.5 (word level, model page), Fun-ASR and Grok (word level in our results) |
| SRT and VTT output | Yes | No | Whisper on Modellix (response_format) until OpenAI shuts it down |
| Translate to English | Yes | No | /v1/audio/translations shuts down with whisper-1 |
| Speaker labels | No | No | Fun-ASR (diarization_enabled), Grok (diarize), Gemini 3.5 Transcribe (diarization) |
Source: OpenAI's migration guide, section 8. Retain whisper-1 for native SRT or VTT and for word or segment timestamps. Speaker labels on OpenAI's API use gpt-4o-transcribe-diarize, not gpt-transcribe.
Compare replacements on one key before you switch
gpt-transcribe is not the only replacement, and the lowest priced model in our test lists at $0.10 an hour against its $0.27. Before you commit, run your own audio through several models and compare transcripts and bills side by side. On Modellix, every model in this article runs on one API key with the same submit and poll flow, so the comparison is a short script:
- Pick one audio URL from your real traffic, ideally a file with names, numbers, or two speakers.
- Submit it to each model. The model path changes, and for two models so does the audio field: Whisper, MAI Transcribe 1.5, and Grok Voice ASR take
url, Gemini 3.5 Transcribe takesaudio, and Fun-ASR takesfile_url. - Poll each
task_id, then compare the transcript and thebilling.amountof each task. - Point production at the model that wins on your audio. Auth, polling, and result handling stay the same.
AUDIO="https://example.com/meeting.mp3"

for m in openai/whisper-1 microsoft/mai-transcribe-1.5 xai/grok-voice-asr; do
  curl -s -X POST "https://api.modellix.ai/api/v1/$m" \
    -H "Authorization: Bearer $MODELLIX_API_KEY" \
    -H "Content-Type: application/json" \
    -d "{\"url\": \"$AUDIO\"}"
done

curl -s -X POST https://api.modellix.ai/api/v1/google/gemini-3.5-transcribe \
  -H "Authorization: Bearer $MODELLIX_API_KEY" \
  -H "Content-Type: application/json" \
  -d "{\"audio\": \"$AUDIO\"}"

curl -s -X POST https://api.modellix.ai/api/v1/alibaba/fun-asr \
  -H "Authorization: Bearer $MODELLIX_API_KEY" \
  -H "Content-Type: application/json" \
  -d "{\"file_url\": \"$AUDIO\"}"
Each call returns a task_id; poll it with GET /api/v1/tasks/<task_id> as in the REST example further down. One limit to plan for: if you depend on SRT or VTT files, none of the four alternatives returns subtitle files directly, so you would build captions from word timestamps yourself.
Same Audio, 5 Transcription APIs: What Each One Billed
We used public-domain audio so anyone can rerun the test: two LibriVox readings with Project Gutenberg texts as the reference, and the first 3 minutes of NASA's Houston We Have a Podcast episode 417 for names and numbers. Every model got each file once. WER counts substituted, missing, and extra words after lowercasing, removing punctuation, and spelling out numbers.
| Model | List price | Billed per hour | WER, 13.4 min | WER, 25.5 min |
|---|---|---|---|---|
| Whisper |
$0.360/hr | $0.360 | 1.72% | 1.44% |
| MAI Transcribe 1.5 |
$0.360/hr | $0.360 | 1.15% | 1.19% |
| Gemini 3.5 Transcribe |
$0.180/hr | list price used¹ | 0.33% | 0.71% |
| Fun-ASR |
$0.126/hr | $0.107² | 1.58% | 1.11% |
| Grok Voice ASR |
$0.100/hr | $0.100 | 1.15% | 2.04% |
¹ Gemini 3.5 Transcribe billed correctly on clips up to 2 minutes. Its five longer tasks finished with a $0 charge, which is a platform billing error, not a price. We use its $0.18 list price everywhere on this page. We have not retested those longer files after a possible billing fix. ² Fun-ASR billed detected speech, not file length (see short files above).

Whisper billed exactly its list price, $0.36 an hour, and was the slowest: 76 seconds to return the 13.4 minute reading and 72 seconds for the 25.5 minute one. Grok Voice ASR returned the same files in 6 and 8 seconds.
Names, numbers, and speakers in a podcast clip
The NASA clip has a host, a guest, a promo read, launch audio, and 20 terms we could check: crew names, NASA programs, dates, mission lengths, and a URL.
| Model | Terms caught | What it got wrong | Speakers found |
|---|---|---|---|
| Whisper |
18/20 | Koch as "Cook", host name as "Niloufar" | No diarization |
| MAI Transcribe 1.5 |
18/20 | Koch as "Cook", host name as "Niloufer" | No diarization |
| Gemini 3.5 Transcribe |
20/20 | None of the 20 | 4, no timestamps returned |
| Fun-ASR |
17/20 | Host name as "nil for randy", Koch as "cook", names in lowercase | 3, six turns with times |
| Grok Voice ASR |
18/20 | Host name as "Nilfa Ramsey", Reid as "Reed" | 2, labels on each word |
Press the sound button on any card to hear the same 26 seconds of the NASA clip: the host introducing herself (0:36 to 0:48) and the crew list (1:48 to 2:01). NASA spells the names Nilufar Ramji and Christina Koch. Each card shows how that model wrote them in its transcript of the full 3 minute clip, from our test run. MAI Transcribe 1.5 is left out here because it spelled the crew name the same way as Whisper (Christina Cook); its result is in the table above. Try any of them in the playground.
A public-domain presidential speech
The same card pattern works for official speeches that are in the public domain. This clip is 19.4 seconds from President Kennedy's inaugural address of January 20, 1961, starting at "And so, my fellow Americans." The recording is public domain: it is published on Wikimedia Commons as public domain, credited to the John F. Kennedy Presidential Library and Museum. The official wording on the card follows the American Presidency Project transcript of the inaugural address. We have not run this clip through the five models on Modellix; that transcription is pending.
Press the sound button to hear the excerpt. The card shows the official transcript, not a model output. Audio: JFK Library / Wikimedia Commons, public domain.

Where the cheaper models slipped
On the 25.5 minute reading, Grok Voice ASR had the highest WER at 2.04%; it turned "rubicund" into "kund" and dropped the "tut, tut" in one line of dialogue. Fun-ASR wrote "Morris" as "Maurice" and "paw" as "poor" in the story whose title is The Monkey's Paw. Whisper made the same "paw" error twice. On the podcast, three of five models heard astronaut Christina Koch as "Christina Cook". Whisper was not the most accurate model in this test: MAI Transcribe 1.5, Gemini 3.5 Transcribe, and Fun-ASR all had a lower WER on both readings.

What one key changes for speech to text
- Switch models by changing the path. Whisper, MAI Transcribe 1.5, Gemini 3.5 Transcribe, Fun-ASR, and Grok Voice ASR all ran from the same key and the same submit, poll, download loop in this test. Moving off Whisper to MAI Transcribe 1.5 or Grok Voice ASR changed nothing else in the request.
- See what each file cost. Every finished task returns `billing.amount`. That is how every billed number on this page was collected.
- Send a URL, not a multipart upload. Pass a public audio link, or upload once to Modellix media storage and reuse the link across models.
Compare the five models on one key →
Whisper API vs Other Speech-to-Text APIs: Price per Hour and How to Choose
| Provider | Model | Per minute | Per hour |
|---|---|---|---|
| OpenAI | whisper-1 | $0.006 | $0.36 |
| OpenAI | gpt-transcribe | $0.0045 | $0.27 |
| Google Cloud | Speech-to-Text V2, dynamic batch | $0.003 | $0.18 |
| AssemblyAI | Universal-2 | $0.0025 | $0.15 |
| AssemblyAI | Universal-3.5 Pro | $0.0035 | $0.21 |
| ElevenLabs | Scribe v2 | $0.0037 | $0.22 |
| Deepgram | Nova-3 Monolingual, pre-recorded (pay as you go) | $0.0043 | $0.26 |
| Modellix | Fun-ASR |
$0.0021 | $0.126 |
| Modellix | Grok Voice ASR |
$0.0017 | $0.100 |
| Modellix | Gemini 3.5 Transcribe |
$0.0030 | $0.180 |
List prices from each provider's pricing page, before volume discounts. Rows marked Modellix are prices on our own platform, from the model pages. The Deepgram row is Nova-3 Monolingual pre-recorded on pay as you go, from the Pre-recorded table on Deepgram pricing.
Pick a Whisper replacement by workload
Each row links to a model page on the same key. Run your own file there, read the transcript, and check what the task billed before you move production traffic.
| Your job | Start with | Why |
|---|---|---|
| Captions with SRT or VTT | Whisper until February 26, 2027 | The only model here that returns subtitle files directly; plan to build captions from word timestamps after that |
| Meetings and interviews with two or more speakers | Fun-ASR or Grok Voice ASR | Both returned speaker turns with times in our podcast test |
| Names, brands, and jargon | Gemini 3.5 Transcribe | Caught all 20 names and figures, lowest WER on both readings |
| Cheapest bulk transcription | Grok Voice ASR | $0.10 an hour list, $0.0995 billed, 1.15% WER on the 13 minute reading |
If your pipeline also turns text back into speech, for example dubbing a transcript or reading it back in a cloned voice, see our MiniMax voice clone guide; it runs on the same API key.
Is self-hosting open-source Whisper cheaper?
The Whisper model weights are open source under the MIT license (openai/whisper on GitHub), so running it yourself has no per-minute fee. You pay for the GPU or CPU time, storage, and the work of keeping a transcription service up. Whether that beats $0.10 to $0.36 an hour depends on how many hours you transcribe and whether the hardware sits idle between jobs. The self-hosted model also keeps working after February 2027, since the shutdown applies to OpenAI's hosted API.
Run whisper-1 and its alternatives on one API key
Whisper on Modellix costs the same $0.36 an hour as OpenAI's list price, so your current workload keeps running while you test replacements next to it. Each model on this page is one path on the same key, which is how we ran this test. These are the ways to call them.
Playground
No code. Open a model page such as Whisper, add an audio file or URL, and the transcript and the task cost show up in your browser.
Coding agent, no install
Paste one sentence into Claude Code, Codex, or Cursor and let it read the docs:
My Modellix API key is mdlx-••••••••••••••••••••••••. Read https://docs.modellix.ai/get-started/index.md and https://docs.modellix.ai/openai/whisper-1.md , then transcribe https://example.com/meeting.mp3 with openai/whisper-1, response_format verbose_json, then run the same URL on xai/grok-voice-asr, google/gemini-3.5-transcribe, alibaba/fun-asr, and microsoft/mai-transcribe-1.5, using each model's own audio field from the docs. Save every transcript to ./transcripts and give me a table of what each task billed.
Swap in your own key from the console, and only share it with agents you trust.
Agent Skill
Install the skill once and your agent reads each model's schema and fills in the request fields itself. Setup is in the Skill guide.
npx skills add https://github.com/Modellix/modellix-plugin --skill modellix-design
Plugin
If your host has a plugin marketplace (Claude Code, Codex, Cursor), the plugin adds the Modellix skills and the Media Generation MCP. In Claude Code, run /plugin marketplace add Modellix/modellix-plugin, then /plugin install modellix@modellix. Other hosts are in the Plugin guide.
CLI
For scripts and cron jobs. One command submits the task, waits, and prints the result. See the CLI guide.
npm install --global modellix-cli
modellix-cli model run --model-slug openai/whisper-1 --body-file request.json --wait
REST API
Submit the audio URL, keep the task_id, and poll until the status is success:
curl -X POST https://api.modellix.ai/api/v1/openai/whisper-1 \
  -H "Authorization: Bearer $MODELLIX_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"url": "https://example.com/meeting.mp3", "response_format": "verbose_json"}'

curl "https://api.modellix.ai/api/v1/tasks/<task_id>" \
  -H "Authorization: Bearer $MODELLIX_API_KEY"
The finished task links to a transcript JSON with text, channels, and duration_ms, plus the amount billed. The audio field is named differently per model (url for Whisper and Grok, audio for Gemini, file_url for Fun-ASR), so check each schema in the API guide.
OpenAI shuts down hosted whisper-1 on February 26, 2027. Modellix has not published whether the openai/whisper-1 listing will be retired, kept, or rerouted after that date, so plan the switch well before then. If you already call Whisper through Modellix, moving to another model on this page is a path change, plus a renamed audio field for Gemini 3.5 Transcribe and Fun-ASR.
Speech-to-text models on the same key
WhisperGrok Voice ASRGemini 3.5 TranscribeFun-ASRMAI Transcribe 1.5
Compare Whisper Replacements on One Key
Send one audio URL to Whisper and four alternatives, then compare each transcript and what the task billed.
Get API KeyOpenAI Whisper API Pricing FAQ (2026)
How much does it cost to use Whisper AI?
The OpenAI Whisper API costs $0.006 per minute of audio, which is $0.36 an hour or $360 for 1,000 hours. The same model costs the same on Modellix. The open-source Whisper model is free to download and run on your own hardware.
Is Whisper free?
The open-source model is free: the code and weights are MIT licensed and run offline on your own machine. The OpenAI Whisper API is not free; the free usage tier only limits how many requests you can send (3 a minute, 200 a day) and you still pay per minute of audio.
How is OpenAI transcription pricing calculated?
By the length of the audio. OpenAI lists an estimated cost per minute for each transcription model, from $0.003 for gpt-4o-mini-transcribe to $0.006 for whisper-1. The 4o models are metered in audio tokens underneath, so a bill can differ slightly from minutes times the rate.
Does Whisper charge a full minute for a 10-second clip?
OpenAI does not publish a rounding rule. On Modellix, Whisper billed per second: our 5 second clip cost $0.0005 and the 31 second clip $0.0031, at the same $0.0001 per second as a 25 minute file.
What is the Whisper API file size limit?
25 MB per request, in mp3, mp4, mpeg, mpga, m4a, wav, or webm. Split longer recordings into parts under that size; splitting does not add cost.
When does whisper-1 shut down, and what should I use instead?
February 26, 2027, together with the translation endpoint and the gpt-4o transcription models. OpenAI recommends gpt-transcribe ($0.0045 a minute) for recorded audio and gpt-live-transcribe for live audio. Among the models we tested on the same audio, Grok Voice ASR had the lowest list price at $0.10 an hour, Gemini 3.5 Transcribe caught all 20 names and figures, and Fun-ASR and Grok Voice ASR returned speaker turns. None of them returns SRT or VTT directly. All five run on one Modellix API key, so you can test them on your own audio before you switch.
Is gpt-4o-transcribe cheaper than Whisper?
No. Both are $0.006 a minute, and both shut down on February 26, 2027. The cheaper current option from OpenAI is gpt-transcribe at $0.0045 a minute.
Related articles
Grok API Pricing: Grok 4.7 Costs Per Call [Tested]
Grok API pricing for Grok 4.7, 4.6 and 4.5: token rates, the 200K long-context rule, caching and tool fees, plus real bills from 23 tested calls.
GPT Image 2.5 Pricing: What Moves the $0.0053–$0.6390 Band
GPT Image 2.5 pricing: what moves the $0.0053–$0.6390 per-image band, why the Edit band starts at $0.0366, and worked budget math.
AI Image Model API Pricing Comparison (2026): 49 Routes
Every live image route on one API key, priced per image as of Sep 15 2026: 49 models, 7 providers, 14 published ranges, and how to check your own bill.
DeepSeek API Pricing (2026): Four Rows, Peak and Cache
DeepSeek API pricing on September 15, 2026: the official peak and off-peak card, all four gateway rows with cache rates, and how to verify what caching saved.