You finish a DeepSeek Harness session, the Trajectory view shows a token count, and you reach for a calculator: was that run worth it? You are not alone in doing mental math at the end of every agent round. In the harness’s GitHub Discussions, a thread asking for a Plus/Pro plan “so we don’t have to calculate the API bill while the agent runs” has 12 comments, and a 1,400-thread scan finds 33 threads whose titles mention price, pricing, cost, or tokens. A thread asking for per-turn token display has 11 comments; another reporting that large contexts inflate token consumption has 22.
This article replaces the mental math with one API call. If you run DeepSeek Harness against the Modellix LLM gateway, a single GET /v1/logs request returns the per-request cost, the token breakdown (prompt_tokens / completion_tokens / cached_tokens), the model that served each call, and enough metadata to attribute spend to a session or an end-user. You will get a runnable query, a field-by-field meaning table, and the per-1M-token conversion the meters never show. Endpoints and prices were verified against docs.modellix.ai and modellix.ai/llm on September 1, 2026. Modellix operates the gateway used in these examples, so we have a commercial interest in this working for you. One boundary up front: this article covers what one run costs and how to see it — choosing models or configuring the provider are separate guides in this series.
Why DeepSeek Harness token usage needs a second source of truth
The harness is not hiding the numbers from you. The Trajectory view exposes token usage alongside model responses and tool calls, and session statistics track turns, steps, model time, tool time, time to first token, and decoding time. A hands-on review of the harness shows live stats such as tokens per second and cache hit rate while a task runs, and the official page advertises that “every run is traceable.”
The problem is what those numbers are. The harness token meter is an estimate — roughly one token per four characters, as a vendor comparison of harness token usage describes it — built for diagnosing where tokens went, not for reconciling what they cost. General deepseek harness usage guides show you how to run the agent; none of them show you what a run costs at the provider. That is why the community keeps asking for more: per-turn token display, per-session accounting, anything that removes the arithmetic. Community shorthand for the whole topic, “dsh token consumption,” shows up across those threads. A proposal to add persistent token-usage tracking to the harness itself (the dsh-token-usage plugin) exists as a GitHub Discussion with one comment — a proposal, not a merged feature. Traceable is not the same as itemized. The meter tells you the shape of the run; the bill lives at the provider that served the requests, and that is where the per-request truth sits.
What one agent run is billed on
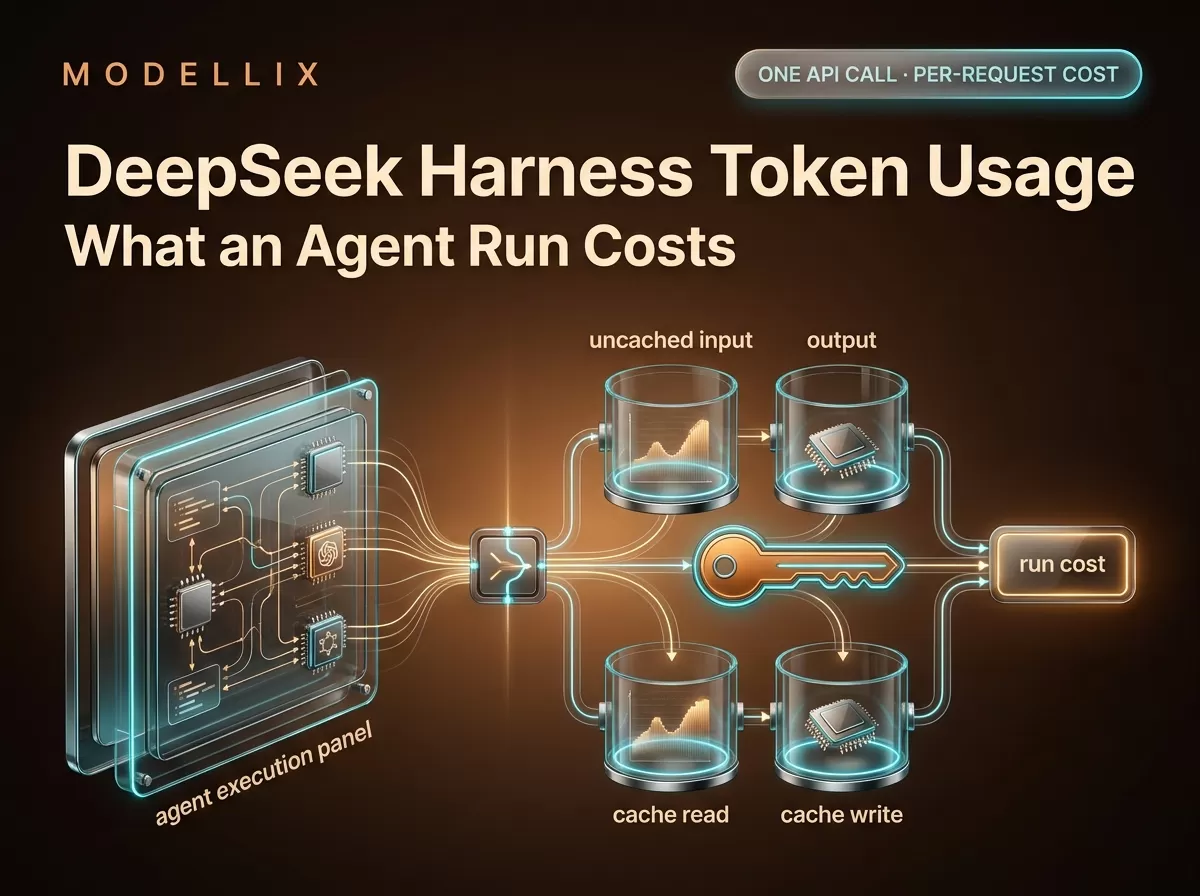
Modellix bills LLM gateway requests from token usage on successful responses. Each request falls into four billed token buckets: uncached input (prompt_tokens), output (completion_tokens), cache read (cached_tokens), and cache write. The logs API exposes per-request fields for three of them; cache write is billed but has no per-request log field. Reasoning tokens are part of the output count, not a separate line. The cost of one run is the sum of each bucket converted at the model’s per-1M-token rate:
1 | run cost = (uncached_input / 1M × input price) |
The per-1M rates for deepseek/deepseek-v4-flash, one of the models Harness ships as a default, were pulled live from the Modellix LLM pricing page on September 1, 2026:
| Model | Input | Output | Cached Read | Cached Write | Discount |
|---|---|---|---|---|---|
DeepSeek V4 Flash deepseek/deepseek-v4-flash |
$0.44 | $1.32 | $0.014 | $0 | — |
DeepSeek V4 Pro deepseek/deepseek-v4-pro |
$1.33 | $3.96 | $0.044 | $0 | — |
Two honest notes on this table. First, the Discount column for V4 Flash is —: there is no promotional discount on it as of the pull date. Second, Cached Read at $0.014 per 1M is roughly 97% cheaper than uncached input at $0.44 — which is why cache hit rate dominates every cost discussion — but Modellix documents that cache read/write pricing applies “when present” and publishes no trigger, TTL, or minimum-token threshold for when a request qualifies. Whether your run hits cache depends on how stable the harness keeps the prompt prefix, and community measurements (for example the 95–100% cache hit rates in the MindStudio hands-on) are harness-side observations, not a gateway guarantee.

The conversion the meters skip: each of the four token buckets is priced per 1M tokens and summed into the run’s cost.
A worked example, illustrative rather than from a real run: a session with 1,000,000 uncached input tokens, 200,000 output tokens, and 3,000,000 cached-read tokens at the V4 Flash rates above costs 1.0 × $0.44 + 0.2 × $1.32 + 3.0 × $0.014 = $0.746. Substitute your own bucket counts from the logs and the same arithmetic gives you your number — the deepseek harness cost question reduced to arithmetic you can verify.
See per-request spend: GET /v1/logs
The logs endpoint lists LLM request logs for your team within a time window, and it is the billing view this article promised. It lives at https://llm.modellix.ai/v1/logs and requires a time window — start_time and end_time are both required UNIX-second timestamps, and the span cannot exceed 30 days. page_size defaults to 10 and caps at 100; page defaults to 1. The API reference documents the full contract.
A directly runnable query — replace the timestamps with your own window and the token with your key:
1 | curl --request GET \ |
The response is a paginated list. Field names and shapes match the API reference; this is an illustrative response:
1 | { |
What each field means:
| Field | Meaning |
|---|---|
cost |
USD cost of that request as billed by the gateway |
prompt_tokens |
uncached input tokens sent in |
completion_tokens |
output tokens generated (reasoning included) |
cached_tokens |
tokens served from cache read |
model.provider / model.model_name |
which provider and model actually served the request |
status / error |
success vs failure; billing is based on usage of successful responses |
created_at / duration / e2e_sec / tps |
request time, duration, and throughput — diagnostics, not billing |
apikeyname |
which API key the request ran under |
input / result |
request/response payloads when retained (see the next section) |

One call, two halves: the query parameters that define your window, and the per-request fields that carry cost and token buckets.
This is the whole “deepseek harness api cost” question in one endpoint: you no longer estimate a run’s cost from the meter — you read it off the row. A run is the set of requests with a shared session; sum their cost fields and you have the run’s price.
GET /v1/logs API Reference
See the full parameter contract, response schema, and error codes for the Modellix LLM request logs endpoint.
View DocsAttribute spend to a session or end-user
Teams share keys, and a shared key turns “what did this cost” into “who spent what.” The logs API answers that too, if the requests carried two optional headers:
X-Mdlx-User-Id— an end-user identifier, 8–128 characters, alphanumeric plus-and_. When requests carry it, the logs endpoint filters on it through themdlx_user_idquery parameter (exact match, same charset rules).X-Mdlx-Session-Id— a session identifier with the same 8–128 character rules. It groups the requests of one agent run. The API guide documents a precedence rule worth knowing: some agent tools send their own session header — Claude Code sendsX-Claude-Code-Session-Id— and when both are present,X-Mdlx-Session-Idtakes precedence.
In practice: give each developer a stable X-Mdlx-User-Id in their harness environment, and one query per user (…&mdlx_user_id=alice-dev) returns that developer’s request rows for the window. Give each run a fresh X-Mdlx-Session-Id and the run’s total is a filter, not a spreadsheet exercise. The dsh-modellix plugin and the custom provider setup both land on the same gateway, so whichever path you used, the same logs cover it.
What the logs will and will not tell you
The endpoint is precise about what it stores, and the boundaries are documented — including the parts that are not. Read these before you build a dashboard on top of the logs:
- Payloads are conditional. The
inputandresultfields are returned only “when retained.” Modellix’s documentation does not state how long payloads are retained, whether retention can be opted out of, or whether retained payloads are used for training — the answers are undocumented as of September 1, 2026. If you need prompt text for audit trails, do not assume it will be there; the token counts andcostare the reliable part. - Cache qualification is undocumented. Cached Read/Write appear in the price table and apply “when present,” but there is no published trigger, TTL, or minimum-token threshold. A
cached_tokensof 0 in your logs does not mean caching is broken — it means that request did not qualify under whatever the platform applies. - Rate-limit headers are hints, not a contract. The documentation says 429 responses may include
X-RateLimit-Limit/X-RateLimit-Remaining/X-RateLimit-ResetandRetry-After— “may,” not “will.” The logs endpoint runs on the query rate limit, which is a separate quota from the inference RPM used by chat requests, so reading your logs does not consume inference quota; exact limits are not published here. - Retries show up as rows. Each API request is one log row. A harness that retries a failing step generates one row per attempt, each with its own token counts and cost — which is how a retry loop becomes visible in the bill.
None of this is a claim that Modellix pricing beats anyone else’s. The value of per-request logs is verifiability: you can check the number yourself instead of trusting a meter, a blog post, or a benchmark.
From log rows to a monthly bill
The path from rows to a bill is mechanical — this is deepseek harness billing reduced to a sum. Pick a 30-day window, page through with page_size=100, sum cost across rows: that is the token spend for that period at the gateway. A few practices make the sums meaningful:
- Dedicated keys per environment or person. A key per developer or per CI runner turns
apikeynameinto a cost dimension you do not have to guess about. - Sessions over spreadsheets. Set
X-Mdlx-Session-Idper run and you can answer “what did yesterday’s refactor cost” with one filtered query. - Watch the retry rows. A loop that retries 20 times is 20 rows of tokens; the logs make it visible before the invoice does.
One boundary: this billing view covers the text LLM gateway. Media generation (image and video models) bills per task or per second, not per token, and is estimated separately in the Modellix media cost calculator — the two are different math and different endpoints. For the harness side of the ecosystem, the agent harness overview places all of this in context, and the DeepSeek Harness pillar article ties the whole series together. If you are still wiring the gateway in, the plugin add guide covers installation end to end.
Open the Modellix Console
Create your Modellix API key and query your own request logs — the first run you price is yours.
LoginFrequently Asked Questions About DeepSeek Harness Token Usage
Does DeepSeek Harness show token usage? The harness shows token estimates in the Trajectory view (tokenUsage, contextPressure, contextBreakdown) and session statistics, and community threads repeatedly request per-turn token display — an 11-comment Discussion asks for exactly that. A third-party plugin proposal (dsh-token-usage) exists, but the official repository has not confirmed built-in per-turn accounting. For billing accuracy, read the provider’s request logs.
What does cached_tokens mean in the logs? It counts tokens served from cache read instead of being billed as fresh input. On Modellix, Cached Read for deepseek/deepseek-v4-flash is $0.014 per 1M versus $0.44 per 1M for input (as of September 1, 2026). Whether a request qualifies for cache is not documented — there is no published trigger, TTL, or minimum-token threshold.
Is the cost field in USD? Yes — cost is the USD cost of the request as billed by the gateway. Rates change, so confirm current pricing in the Modellix console before relying on a number.
How far back can I query logs? start_time and end_time are both required, and the span between them cannot exceed 30 days. Paginate with page and page_size (default 10, maximum 100).
Can I filter logs by user? Yes — pass mdlx_user_id as a query parameter; it is an exact match against the X-Mdlx-User-Id header sent on inference, with the same 8–128 character rule (alphanumeric plus - and _).
Do failed requests cost money? Billing is based on token usage of successful responses. Log rows include status and error per request, so failures are identifiable in the log even though they are not the billed ones.
Will reading logs slow down my agent? No — the logs endpoint runs on the query rate limit, which is a separate quota from the inference RPM used for chat requests. Reading logs does not consume inference quota.
How do I attribute costs to one Harness session? Send X-Mdlx-Session-Id on the requests. If Claude Code’s own X-Claude-Code-Session-Id is also present, X-Mdlx-Session-Id takes precedence per the API guide, so the session you name is the session that lands in the logs.
Endpoints, pricing, and rate-limit wording reflect Modellix public documentation as of September 1, 2026, and change as the platform evolves; confirm live rates in the Modellix console before committing. Access DeepSeek and 200+ other models through a single API key at modellix.ai.